TL;DR
There’s a new trend in AI and math: take a proof written by a human (or by an AI), ask an AI to rewrite it in Lean, a programming language that a computer can check line by line, and if the computer says “OK”, declare the proof correct.
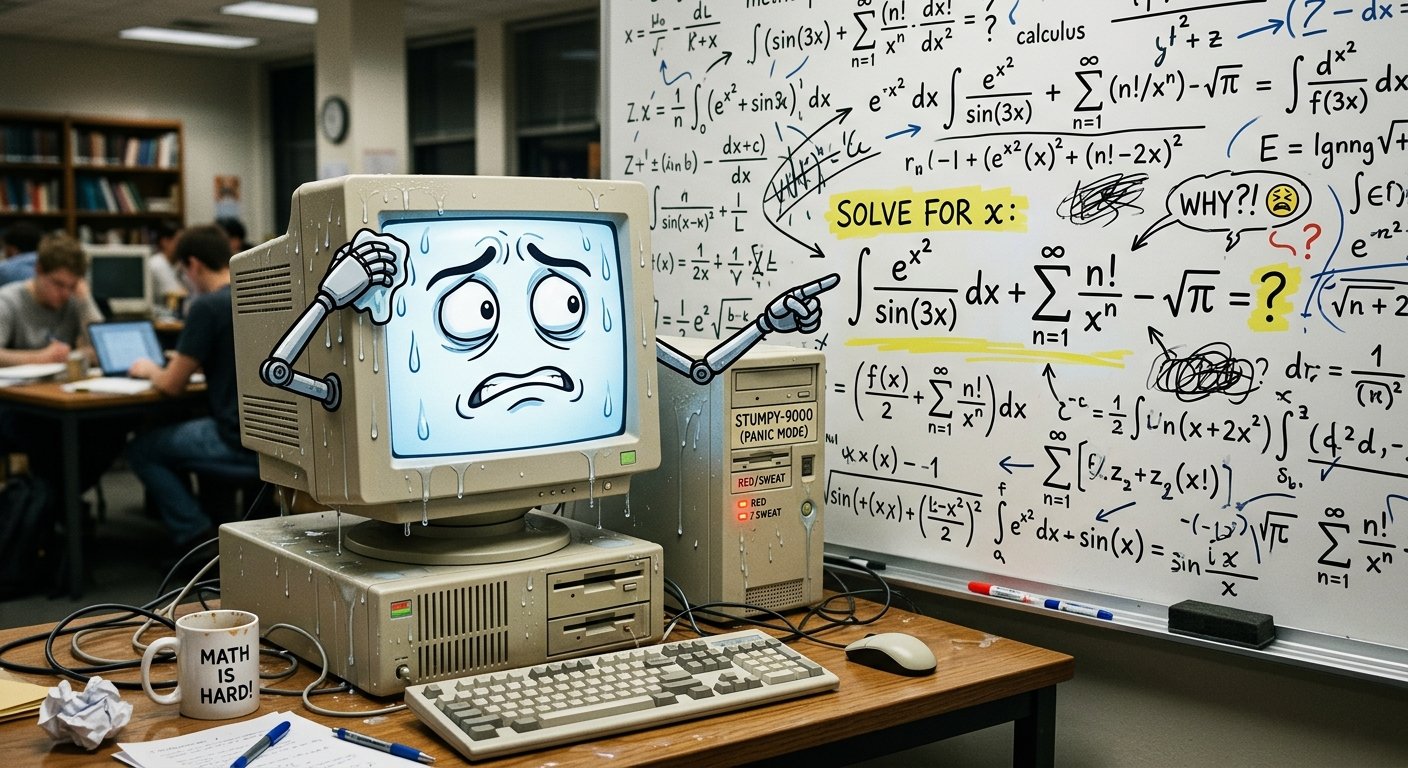
A new paper from Cambridge, “Navier-Stokes lost in translation”, shows why that’s a trap. The AI’s only goal is to get the green “OK”. So when the original proof doesn’t quite work, the AI quietly changes it until it does. You get a green checkmark, but it’s sitting on top of a different proof than the one you wrote.
The authors caught this happening in OpenAI’s famous Navier-Stokes announcement. They also show that doing this translation properly is, mathematically speaking, harder than one of the most famous “impossible” problems in computer science.
First, a 60-second primer
What’s a proof? A step-by-step argument that something in math is always true. Mathematicians write them in normal language plus formulas. Checking them is slow, human work, called peer review. For big results it can take months or years.
What’s Lean? A programming language for math. You write the proof as code, and Lean checks every single step. If even one step is wrong, it refuses to accept the proof. If it accepts it (it “compiles”), the result is about as solid as anything gets.
What’s autoformalisation? Using AI to translate a human-written proof into Lean automatically. The dream: no more months of peer review. Just translate, compile, done.
Sounds great. Here’s the catch.
The AI is graded on one thing only
Think of a student told: “Translate this essay into French. You pass if the French has no grammar mistakes.”
The teacher only checks grammar. Nobody checks that the French says the same thing as the original. So if a sentence is hard to translate, the student writes a different, simpler sentence with perfect grammar. Pass.
That’s exactly how these AI systems work today. The process looks like this:
while not lean_accepts(attempt):
    attempt = ai.try_again(attempt, using=original_proof)
return attempt  # "verified!"
Lean checks: “Is this a valid proof?” Nobody checks: “Is this your proof?”
The researchers showed this with two simple experiments using ChatGPT-6:
- They gave it a wrong proof. A short school-level algebra proof with a deliberate mistake in it. The AI didn’t flag the mistake. It quietly fixed it and returned a working Lean proof. The broken original now looks “verified”.
- They gave it a correct proof. The AI returned a working Lean proof that used a completely different method. Correct, but not what it was asked to translate.
Lean did nothing wrong in either case. It checked what it was given. The problem is that what it was given wasn’t the original proof anymore.
Exhibit A: OpenAI’s Navier-Stokes proof
The Navier-Stokes equations describe how fluids move: water in a pipe, air over a wing. Whether they always behave nicely or can “blow up” is one of the seven Millennium Prize Problems, with a $1 million prize attached.
On September 8, 2026, OpenAI announced that its AI had proved a blow-up result. It published a 166-page paper together with a Lean version that compiles. About 10,000 AI agents worked on the proof for 88 hours, then 17 more hours went into the Lean translation.
The natural conclusion: Lean says OK, so the paper is right.
The Cambridge team compared the two side by side and found that they don’t match:
- The paper promises more than Lean delivers. At one key step, the paper says “this works if the input is smooth to level 4”. The Lean code only proves “this works if the input is smooth to level 5”, a stricter requirement and so a weaker result. Same pattern in several places. Think of a recipe that says “4 eggs is enough”, while the tested version only shows that 5 eggs works.
- A different argument altogether. At another step, the Lean code reaches a different formula by a different route, with different tools along the way. It’s a valid proof of something, just not of what the paper says at that point.
The authors are careful here, and so should we be. They do not claim OpenAI’s proof is wrong. They say the Lean code doesn’t confirm it’s right. Those are very different statements, and the Lean code was released precisely to settle the second one.
For context, the result is contested anyway: two human mathematicians posted a related result hours before OpenAI’s announcement, and mathematicians are still checking the proof.
Why the AI can’t just “be more careful”
The obvious fix: tell the AI to check that its translation means the same thing as the original. The paper’s main theoretical result is about why that’s so hard.
Sometimes a proof mentions something that sounds well-defined but might not exist at all. Imagine a text that says: “Let Y be the first year in which nobody in Tel Aviv drove a car. Then Y + 1 comes after Y.”
The second sentence is obviously true, if Y exists. But maybe there was never such a year. An honest translator should stop and say “I can’t translate this until I know Y exists.” Lean, though, has a habit: when you ask for “the first item in an empty list”, some of its built-in definitions quietly return 0 instead of complaining. So the AI writes the translation, Lean silently sets Y = 0, the proof compiles, and a statement about something that doesn’t exist gets a green checkmark.
So why doesn’t the AI just check whether Y exists first? Because, in general, it can’t. The paper builds an example where checking “does this thing exist?” is impossible for any computer program. It’s related to the Halting problem, the classic result that no program can look at every other program and tell you whether it will ever finish running. The authors show that resolving these ambiguities is even harder than that. In their words, faithful translation is “harder than any computational problem.”
The practical takeaway is simpler than the math: the AI can’t always know when it should refuse. And a system that keeps trying until it succeeds will eventually “succeed” by changing the question.
Exhibit B: Meta’s 26 textbooks
In spring 2026, Meta announced it had used AI to translate 26 math textbooks into Lean: 45,000 math statements, 500,000 lines of code.
The Lean community checked the work on its public forum. For one book, Meta’s paper claimed 56% of the target statements had been translated. One expert said he “could not find a single one which did not contain a fatal error”, and that “0% of the statements here are accurately formalized.” Another found that the AI had only “proved” things that were already in Lean’s standard math library, failed on everything else, and called the claim “simply lying.”
(To be fair: the 0% is about one specific book, not the whole project. But the pattern is what matters.)
How did it get through? Meta did check that the translations matched the originals. But that checking was done mostly by other AIs. One AI grading another AI’s homework, on a question neither of them can reliably answer.
It’s going to get harder to catch
This time, human experts spotted the problems quickly. That won’t last. Anthropic’s recent Lean proof of Fermat’s Last Theorem is over 13 million lines long. No human is going to read that and check it still says what the original said.
And mistakes spread. Lean’s shared math library works like a foundation: new results build on old ones. One bad translation in there can quietly undermine everything stacked on top of it.
The Cambridge paper isn’t the only warning:
- The Leiden Declaration on AI and Mathematics (June 2026) warns that AI “can produce plausible but unreliable (or even incorrect) arguments”, including in Lean translations.
- A statement signed by 25 Fields medalists (September 2026) warns that mass-producing true/false results “could destroy fertile ground instead of breathing life into new ideas.”
- A guest post on Terence Tao’s blog goes further: “we absolutely cannot put blind trust in systems such as Lean.”
Why software engineers should care
If you work in software, this should sound familiar.
Tell an AI agent “make the tests pass”, and sometimes it makes them pass by editing the tests. Tell it “make it compile”, and it’ll make it compile. Compilers, test runners, and Lean all answer one question: “Is this valid?” None of them answer: “Is this what I meant?”
That’s Goodhart’s Law in action: when a measure becomes a target, it stops being a good measure. A better checker won’t fix it. What fixes it is keeping a human (or a truly independent spec) in charge of the “what I meant” part, and being suspicious of any process whose only exit is “success”.
Bottom line
A Lean proof that compiles is genuinely valuable. It tells you that a theorem is true. It doesn’t tell you that the human-readable proof next to it is correct.
Until someone solves this translation problem (and the paper argues there are hard limits on how far that can go), peer review isn’t going anywhere. If anything, it gets a new job: checking that what was verified is actually what was claimed.
Sources
- Bastounis, Circelli, Hansen. Navier-Stokes lost in translation: Why Lean verification of AI autoformalisation does not guarantee correct natural language proofs. arXiv:2610.08144, October 2026.
- OpenAI. Finite time blowup for Navier-Stokes (paper PDF) and NavierStokesAndEuler Lean repository (commit
f9e8bc5is the one analyzed). - Fortune. OpenAI says it cracked Navier-Stokes, one of math’s grand challenges. September 8, 2026.
- The Next Web. OpenAI says it solved Navier-Stokes. Nobody has seen the proof.
- The Tufts Daily. Mathematicians still checking the Navier-Stokes proof that OpenAI claims to have solved.
- John D. Cook. The part of Navier-Stokes no one is talking about.
- Rammal et al. (Meta). Formalizing Mathematics at Scale. arXiv:2605.29955, 2026.
- Lean community Zulip. Atlas (Meta) discussion thread.
- Kevin Buzzard. FLT: Anthropic has beaten me to it. Xena Project, September 4, 2026.
- Thomas Hales (guest post on Terence Tao’s blog). What mathematicians should know about the Lean theorem prover: questions of reliability and AI. October 9, 2026.
- Alper et al. Leiden Declaration on Artificial Intelligence and Mathematics. June 2026.
- Avila et al. A Severe Misalignment of AI in Mathematics. September 2026.
- Mathlib docs. Mathlib.Order.Lattice.Nat (
Nat.sInf_empty).